Pevita Pearce
For years, the promise of personal computing has been a machine that understands, assists, and communicates with us in a way that feels human. While we have made massive strides in the "understanding" department—thanks to the proliferation of powerful local large language models (LLMs)—the "speaking" department has remained largely tethered to the cloud. High-quality, natural-sounding text-to-speech (TTS) engines have historically been locked behind restrictive subscription paywalls or hidden behind clunky API calls that necessitate a constant internet connection and a sacrifice of user privacy.
Ollama, the open-source platform that has become the gold standard for running local AI models, is dismantling this paradigm. With its latest integration of the Phonon model family, Ollama is bringing high-fidelity, natural-sounding AI voices directly to your Mac. This move marks a significant shift in the landscape of local AI, moving us closer to a future where your computer is not just a processor of data, but a conversational partner that operates entirely offline.
The Core Innovation: What is Phonon?
At the heart of this update is Phonon, a suite of small, highly efficient voice models developed by Gradium. Designed specifically to run on local hardware, Phonon represents a breakthrough in the efficiency-to-quality ratio.

Unlike massive cloud-based models that require server farms to generate speech, Phonon models are optimized for consumer hardware. By leveraging Apple’s powerful MLX framework—a machine learning library specifically engineered for Apple Silicon—Ollama has managed to squeeze impressive performance out of these models. According to early benchmarks, the integration runs 35% faster than Gradium’s standard runtime on a MacBook Pro equipped with the M5 Max chip, all while maintaining absolute parity in vocal accuracy and clarity.
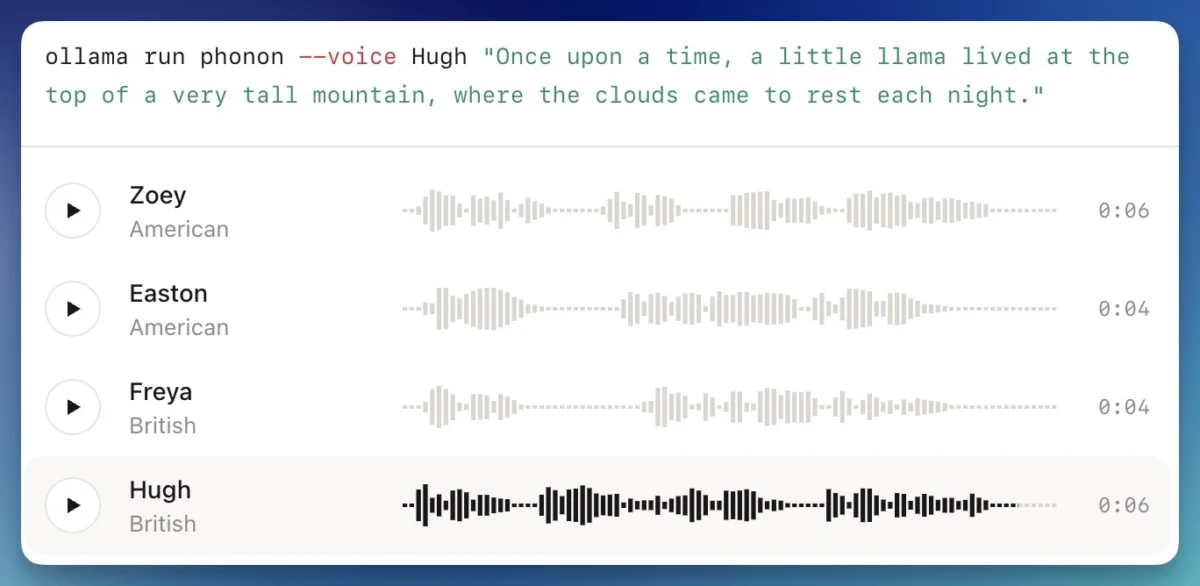
This is not just about raw speed; it is about the "feel" of the interaction. The voices, ranging from the warm tones of Zoey and Freya to the more authoritative deliveries of Easton and Hugh, offer both American and British English accents. Furthermore, the model family supports a diverse linguistic array, including German, French, Spanish, and Portuguese, ensuring that this tool isn’t just for a niche English-speaking audience.
A Chronology of the Local AI Revolution
To understand the magnitude of this development, one must look at the rapid evolution of the local AI ecosystem over the past 24 months:

- Early 2025: The rise of local LLMs like Llama 3 and Mistral began to prove that high-end intelligence could reside on a laptop. However, users were mostly limited to text-based interaction.
- Mid-2025: Tools like TypeWhisper brought advanced speech-to-text (STT) capabilities to macOS, allowing users to dictate with high precision without cloud dependencies. The "input" side of the equation was solved, but the "output" remained a bottleneck.
- Late 2026: Ollama announces the support of Phonon. This serves as the missing piece of the puzzle, bridging the gap between local processing of thought (LLMs) and local expression of speech (TTS).
- October 2026 (Present): The rollout begins on macOS, with Windows and Linux support currently in the pipeline.
This trajectory highlights a clear trend: the industry is moving away from centralized, subscription-based AI services toward decentralized, privacy-first local computation.
Performance and Technical Specifications
The technical prowess of the Phonon integration lies in its implementation. By integrating directly into the Ollama architecture, the TTS engine functions with minimal latency. Users can pair these voice models with any chat model currently supported by Ollama.
A standout feature is the "streaming" playback. In most conventional AI setups, the user must wait for the entire response to be generated and synthesized before hearing a single word. With the new Ollama update, playback begins as soon as the first sentence is generated. This creates a fluid, near-instantaneous conversational loop that mimics the cadence of human speech.

Requirements for Users
To take advantage of this technology, users must meet the following criteria:
- Hardware: An Apple Silicon-powered Mac (M1, M2, M3, M4, or M5 series).
- Software: Ollama version 0.40.11 or later.
- Licensing: While the core English models are provided under the permissive Apache 2.0 license, users should be aware that the French, German, Spanish, Portuguese, and multilingual variants are currently restricted to non-commercial, personal use.
Implications: The Privacy Dividend
The most profound implication of this technology is the death of the "privacy trade-off." Historically, if you wanted high-quality AI speech, you had to upload your text to a server owned by a third-party corporation. Those corporations then used that data to train future models or, at the very least, logged your interactions for metadata analysis.
With Ollama and Phonon, the entire pipeline—from the moment you type a prompt to the moment the computer speaks the answer—occurs within the "air-gapped" environment of your device. Your data is never transmitted, never stored on a server, and never used to train someone else’s model. For journalists, lawyers, researchers, and privacy-conscious professionals, this is the first time they can truly utilize AI tools without exposing their sensitive information to the cloud.

The Broader Landscape of Localized AI
Ollama’s move arrives at a time when the tech industry is under increasing scrutiny regarding data handling. Recent research, such as the development of the ORISA forensic tool, has shown that "deleting" an AI conversation from an app often leaves behind a digital footprint that can be reconstructed by sophisticated tools. By keeping the entire ecosystem local, Ollama eliminates the possibility of cloud-side data recovery, offering a level of digital hygiene that cloud-based competitors simply cannot match.
Furthermore, the hardware-specific optimizations we are seeing—like the use of the M5 Max’s neural engine to accelerate Phonon—suggest that the future of computing will be defined by the synergy between bespoke hardware and open-source software. As Apple continues to push the boundaries of its Silicon, and as projects like Ollama continue to refine their software to exploit that hardware, the distinction between "local software" and "supercomputing power" continues to blur.
Challenges and Future Outlook
Despite the excitement, there are hurdles to overcome. The most immediate is cross-platform parity. While Mac users currently enjoy the fruits of the MLX framework, Windows and Linux users remain in a waiting period. The challenge for the developers will be ensuring that the 35% speed increase seen on Apple Silicon can be replicated on heterogeneous PC hardware, which often lacks the unified memory architecture that makes Apple’s chips so efficient for AI workloads.

Additionally, while the voice models are remarkably natural, they are not yet perfect. Nuance, emotional inflection, and long-form narrative delivery are areas where current models still struggle compared to human voice actors. However, given the pace of development in the open-source community, these issues are likely to be addressed in upcoming iterations.
Conclusion
The integration of Phonon into the Ollama ecosystem is a watershed moment for personal computing. It represents the maturation of local AI, moving it from a hobbyist’s curiosity to a functional, daily-driver tool for productivity. By removing the need for cloud-based subscriptions and ensuring total data privacy, Ollama is not just offering a new feature; it is setting a new standard for how we should interact with our machines.
As we look toward the end of 2026, the question is no longer whether we can run AI locally, but rather, why we would ever choose to run it anywhere else. The era of the silent, subservient computer is coming to a close, replaced by a new generation of devices that can listen, think, and—now, more than ever—speak for themselves.

 Dwi Wanna
 Nana Muazin